For years, the relationship between humans and artificial intelligence (AI) followed a straightforward pattern: people gave instructions, and machines responded, but as large language models (LLMs) have become more lifelike, empathetic and responsive, a new behaviour has emerged: sustained verbal abuse and cruelty directed at AI systems.
In late 2026, Anthropic became the first major AI company to explicitly prohibit “sustained and needless abusive or cruel behavior” towards its chatbot, Claude, marking a potential shift in how the industry approaches human interactions with AI.
While companies such as OpenAI, Google and Meta have policies restricting the use of AI to harm or harass people or generate hate speech, Anthropic’s approach extends the discussion to how users treat the AI models themselves and the dynamics of human-machine conversations.
This is not cruelty in the conventional sense, however, because AI systems do not experience emotions or psychological distress in the way humans do.
To understand why technology companies are beginning to set boundaries around how people interact with AI, two questions need to be examined:
What does abusive behaviour towards a large language model actually look like?
What effects can such behaviour have on the user, the AI model’s responses and the technology behind it?
Artificial intelligence is helping scientists design potential medicines in ways that were once difficult to imagine, but the biggest challenge remains proving that they work in people.
Imagine a future in which scientists can find promising treatments for diseases faster, test fewer unsuitable compounds and explore medicines for conditions that have received little research attention.
Artificial intelligence (AI) could help bring that future closer, although it has yet to prove that it can reliably deliver safer, more effective medicines at scale.
Developing a new drug is a long, expensive process that involves identifying a disease mechanism, designing a potential treatment, testing it in laboratories and animals, and conducting clinical trials in people. Many promising candidates fail because they prove ineffective or cause unacceptable side effects.
AI offers a new way to approach the earliest stages of this process.
Instead of relying entirely on researchers to identify and test potential chemical compounds one by one, AI systems can analyse vast amounts of biological and chemical data, predict how molecules might behave and suggest candidates worth investigating.
Think of it as a research assistant capable of searching through an enormous library of possibilities, although its predictions must still be checked in the real world.
A promising breakthrough in lung disease
One important example emerged in June 2025, when researchers published results from a clinical trial of rentosertib, an experimental drug developed using generative AI to treat idiopathic pulmonary fibrosis, a progressive lung disease that causes scarring and makes breathing increasingly difficult.
The study, published in “Nature Medicine”, involved 71 patients and tested the drug against a placebo over 12 weeks.
Patients receiving the highest once-daily dose showed an average improvement of 98.4 millilitres in forced vital capacity, a measure of how much air a person can exhale, while the placebo group recorded an average decline of 20.3 millilitres.
The results were encouraging, but the trial was small and relatively short, and the researchers said larger studies were needed to establish whether the treatment was effective and safe over longer periods. The drug is experimental, not an approved treatment.
What does the latest research tell us?
A study published online in October 2026 identified 129 AI-enabled drug candidates that had entered human clinical trials by March 2026, spanning 69 companies.
However, only five candidates had reached or completed phase three trials, the later stage of testing that typically involves larger groups of patients.
The findings suggest that AI is helping generate potential medicines, but there is still limited evidence that these candidates can consistently survive the later stages of drug development.
A separate review published in Nature Reviews Drug Discovery in August 2026 reached a similarly cautious conclusion, arguing that evidence of AI’s impact on clinically meaningful outcomes remains limited.
The real test is still ahead
AI could eventually help researchers identify new treatments for cancer, rare diseases and conditions for which existing medicines offer limited relief.
But predicting how a molecule might behave is not the same as proving that it will help a patient. Human biology is complex, and a drug that looks promising on a computer can fail when tested in the body.
There are also questions about whether faster discovery will translate into lower medicine prices or better access for patients.
For now, AI is best understood as a powerful new tool for scientists, rather than a replacement for them.
The breakthrough worth watching is not simply whether AI can design a drug, but whether it can help deliver medicines that are demonstrably safer, more effective and accessible to the people who need them.
Reference:
Xu et al., A generative AI-discovered TNIK inhibitor for idiopathic pulmonary fibrosis: a randomized phase 2a trial, Nature Medicine, 3 June 2025. Read the study.
Artificial intelligence-enabled drug discovery: A growing but largely early-stage clinical pipeline, Cancer Treatment Reviews, published online 8 October 2026. Read the research.
Bender et al., Artificial intelligence in drug discovery: what it is, where we stand and the path forward, Nature Reviews Drug Discovery, 7 August 2026. Read the review.
Reuters, US government, Google join Zuckerberg-backed Biohub in $1.8 billion push for AI biology data, 7 October 2026. Read the report.
Using artificial intelligence (AI) tools such as ChatGPT to solve problems may make people less willing to persevere when the technology is unavailable, according to new research involving 1,222 participants.
The study, co-authored by Brian Christian, a research fellow at the University of California, Berkeley’s Center for Human-Compatible AI, found that people who relied on AI assistance struggled more with independent problem-solving after the tool was withdrawn, raising questions about the long-term effects of using chatbots for everyday tasks.
Researchers conducted three randomised controlled experiments involving participants who tackled maths problems and reading comprehension exercises, comparing those who could use AI with people who had to work without it.
In the first experiment, involving 354 people, one group solved basic fractions with ChatGPT available for assistance, while another worked independently, and researchers removed AI access from the first group after 12 questions.
Although the AI-assisted participants initially achieved greater accuracy, their performance deteriorated sharply when they had to continue without the tool, while those who had worked independently maintained their progress.
The 2nd experiment
A second experiment involving 667 participants produced similar results, with people who had relied on AI more likely to answer incorrectly or abandon questions after losing access to assistance.
The researchers also tested 201 participants on a reading comprehension exercise, finding that AI users again showed reduced accuracy and persistence when they had to work independently.
The findings suggest that AI can change not only how accurately people complete a task but also how willing they are to keep trying when a problem becomes difficult.
Christian said the results highlighted the danger of tools that deliver answers instantly, potentially making the slower process of thinking through a problem feel unnecessarily frustrating.
Researchers describe this effort as “productive struggle”, arguing that working through difficulties can help people develop skills, discover interests and build expertise.
The implications extend beyond classrooms, as professionals and researchers increasingly use AI to speed up their work, potentially sacrificing opportunities to develop independent judgement and understanding.
Christian argued that AI systems should be designed to teach users rather than simply provide answers, helping people strengthen their abilities instead of replacing the mental effort needed to acquire them.
The study, presented at the Conference on Language Modeling in October, does not establish that all AI use damages cognitive abilities, but it raises concerns about what happens when people routinely outsource difficult thinking to machines.
Artificial intelligence (AI) can make hours of police body-camera footage searchable within minutes, but new research warns that transcription errors could distort investigations, undermine accountability and change how encounters between officers and civilians are understood.
A study published in the ‘Journal of Experimental Criminology’ found that AI transcription software captured much of the language recorded by police body-worn cameras but struggled to identify individual speakers accurately, particularly during complicated exchanges involving several people.
Researchers examined 176 body-camera videos covering 73 incidents and approximately 23 hours of footage collected by the Kansas City Police Department in Missouri between January and March 2024. They compared transcripts generated by Rev.ai, the speech-recognition technology behind Axon’s automated transcription service, with versions edited by professional human transcribers.
The AI-generated transcripts identified an average of 3.3 speakers per document, compared with 4.8 in the human-edited versions, and never identified more than seven speakers, while human-edited transcripts recorded as many as 16.
The software also produced transcripts containing approximately 25,000 fewer words across the sample, suggesting that background conversations, radio communications and contributions from less prominent speakers were frequently omitted.
What is still wrong
The problem was not simply that the technology missed words, but that it sometimes attributed statements to the wrong person, potentially changing the meaning of an encounter.
In one example, a tense exchange between a police officer and a civilian was largely transcribed correctly, but the AI system combined statements from both people and presented them as if they had come from one speaker.
Such mistakes could have serious consequences when transcripts are used to investigate allegations of misconduct, assess the use of force or evaluate whether officers communicated respectfully with members of the public.
The researchers argue that AI transcription remains useful for searching large volumes of recordings, identifying keywords and flagging encounters for further examination, but should not replace human review when accurate speaker identification matters.
The technology offers a practical solution to a significant problem: the Kansas City police department can generate more than 350 hours of body-camera footage in a single day, making comprehensive manual review difficult.
However, the study has limitations because it examined footage from one police department and assessed a single AI transcription provider, meaning the findings may not apply equally to other systems.
The researchers also acknowledged that the human-edited transcripts began with AI-generated drafts, rather than being produced independently from the original recordings.
The findings highlight a broader challenge for artificial intelligence in criminal justice: a system can reproduce most of the words in a recording while still misrepresenting the interaction itself.
Google has launched an experimental platform that allows people to create and play their own video games using artificial intelligence, potentially opening game development to people without coding or technical experience.
Playground, unveiled on Wednesday, lets users describe a game idea through text prompts and then build it directly in a web browser. Users can start with a blank canvas, modify suggested concepts or use guided prompts to develop their ideas.
The platform allows creators to change elements including characters, game rules, physics and environments simply by telling the AI what they want to alter. Google said creators remain in control of the creative direction, from the initial concept through to the finished game.
The games can then be played privately, shared with friends through a link or published to Playground’s community gallery, where other users can discover and play them.
Google said Playground also supports multiplayer games in selected genres and includes leaderboards, allowing players to compete and follow creators. Games published to the gallery will undergo safety screening based on Google’s community guidelines, with users also able to report content.
The browser-based platform is designed to work across devices, allowing users to play games on smartphones and laptops rather than requiring specialised software or hardware.
Google is also planning a more advanced route for creators through Unity Spark, an integration that will bring professional-level game mechanics, high-fidelity 3D capabilities and the Unity runtime to Playground.
Unity Spark is currently being tested, with a closed beta planned, potentially allowing games that begin as simple AI-generated experiments to evolve into more sophisticated experiences.
Google described Playground as an early experiment aimed at making game creation more accessible and encouraging everyday creativity.
The platform launched on Wednesday for users aged 18 and over in the US, with access to game creation being rolled out in tiers based on Google One membership.
If an AI agent is managing some or all of your finances, treat it like a highly capable assistant, not a replacement for your judgement. An AI can move money, pay bills, compare investments or make trades, but it can also make mistakes at remarkable speed.
The first precaution is to limit what the agent can do. Give it only the permissions it needs, much like giving a house sitter one key rather than handing over your entire keyring. An agent that only needs to pay bills should not automatically have permission to transfer large sums or trade investments.
Set clear financial limits. Put spending caps, transfer limits and approval requirements around important transactions. For example, you might allow an agent to pay a £100 electricity bill automatically but require your approval before it transfers £5,000.
Keep an emergency brake. Make sure you can quickly revoke the agent’s access, freeze accounts or disable automated transactions. This is similar to having a circuit breaker that cuts electricity when something goes wrong.
Do not let an AI become the sole guardian of your money. Keep separate access to bank and investment accounts, maintain emergency savings that are not controlled by the agent and review statements regularly. Think of the AI as a co-pilot: it can handle much of the routine work, but you should remain capable of taking control.
Be particularly careful with investment decisions. AI can analyse huge amounts of information, but it can misunderstand market conditions, rely on inaccurate data or act on instructions it has interpreted incorrectly. Require human approval for large or unusual trades.
Finally, protect the AI account itself. Use a strong, unique password and multi-factor authentication, and be cautious about connecting new services or approving unfamiliar requests.
The central rule is simple: automate routine decisions, but keep humans in charge of consequential ones. The more money an AI can move, the more safeguards should stand between its recommendation and your bank account.
Here’s the quick checklist
Limit the AI agent’s access to only the accounts and services it needs.
Set spending, transfer and trading limits, with human approval required for large transactions.
Keep an emergency brake so you can quickly revoke access or freeze transactions.
Maintain separate savings and accounts that the AI cannot control.
Review bank statements, payments and investment activity regularly.
Require human approval for large, unusual or high-risk investments.
Check the information the AI uses before acting on major financial decisions.
Protect the AI account with a strong, unique password and multi-factor authentication.
Be cautious when connecting new financial services or approving unfamiliar requests.
Treat the AI as a co-pilot, not the person in charge of your finances.
Today, we try and understand what “Reality drift” means.
It describes the gradual erosion of the boundary between what is created by humans and what is generated by artificial intelligence (AI), making it increasingly difficult to distinguish authentic material from synthetic content.
The term applies to a world in which AI-generated images, videos, voices, articles and social media posts become sufficiently convincing that people can no longer rely on appearance, sound or writing style to establish whether something is real.
Reality drift is different from a conventional deepfake because it does not necessarily involve deliberate deception, and instead describes a broader change in the information environment.
As generative AI becomes embedded in search engines, social networks, advertising, entertainment and news production, synthetic material can become part of everyday communication without being clearly identified as machine-generated.
This creates a problem of accumulated uncertainty, because people may begin questioning genuine material as well as fabricated content.
A photograph of a political event, for example, can be dismissed as AI-generated even when it is authentic, while a synthetic image can acquire credibility simply because it appears plausible.
The effect is not only technological but psychological, as repeated exposure to synthetic media can change people’s expectations about what reality looks and sounds like.
Reality drift can also affect journalism, politics and personal relationships by weakening the evidential value of photographs, recordings and written testimony.
The central danger is therefore not that AI will make every piece of information false, but that it could make certainty increasingly difficult to achieve.
Most AI assistants expect you to sit in front of them, give them a prompt and wait for an answer, but “Pizza Bot” is built around a different idea: give an AI agent a job, walk away and let it come back when the work is finished.
Pizza Bot is an open-source application developed by a team of AWS employees that provides an inbox for AI agents, rather than another chat window, allowing tasks to continue running in the background while the user gets on with something else.
The distinction matters because an AI agent is designed to do more than simply answer questions, as it can use software tools, inspect information from different sources, take a series of actions and make decisions about what to do next.
Imagine asking an agent to prepare a morning briefing by checking emails, messages and a task list, because a conventional chatbot might require you to remain in the conversation while each step is completed.
Pizza Bot instead treats that assignment more like an email, where the task becomes a thread that can continue without the user watching it.
How it works
The agent can work in the background, run scheduled tasks or respond to webhooks, which are automated signals from other software, and it can hand parts of a job to specialised agents.
Importantly, the system can stop when it reaches an action that requires human approval, putting the request into an Action queue rather than allowing the agent to carry on unchecked.
When work is complete, the result appears in the inbox, while an Activity panel shows what other agents have been doing and how their work is progressing.
Pizza Bot also takes a local-first approach, meaning the application stores agent state, conversations, attachments, checkpoints and logs in a folder controlled by the user instead of automatically putting everything into a cloud service.
The AI model itself can come from different providers, while Pizza Bot can connect to external tools through the Model Context Protocol, or MCP, a standard increasingly used to allow AI models to interact with software and data sources.
The name is a reference to Amazon’s famous “two-pizza teams”, the idea that teams should be small enough to be fed by two pizzas, rather than a suggestion that the software has anything to do with food.
The concept
The bigger idea behind Pizza Bot is that AI agents may eventually become less like chatbots and more like digital colleagues that receive assignments, work independently and return with results.
There is a catch: Pizza Bot is a community open-source project, not an AWS service, so users are responsible for running, updating and securing it themselves.
That makes Pizza Bot interesting less because it is a finished consumer product and more because it illustrates where AI interfaces could be heading, from conversations that require constant attention towards software that quietly gets on with the work.
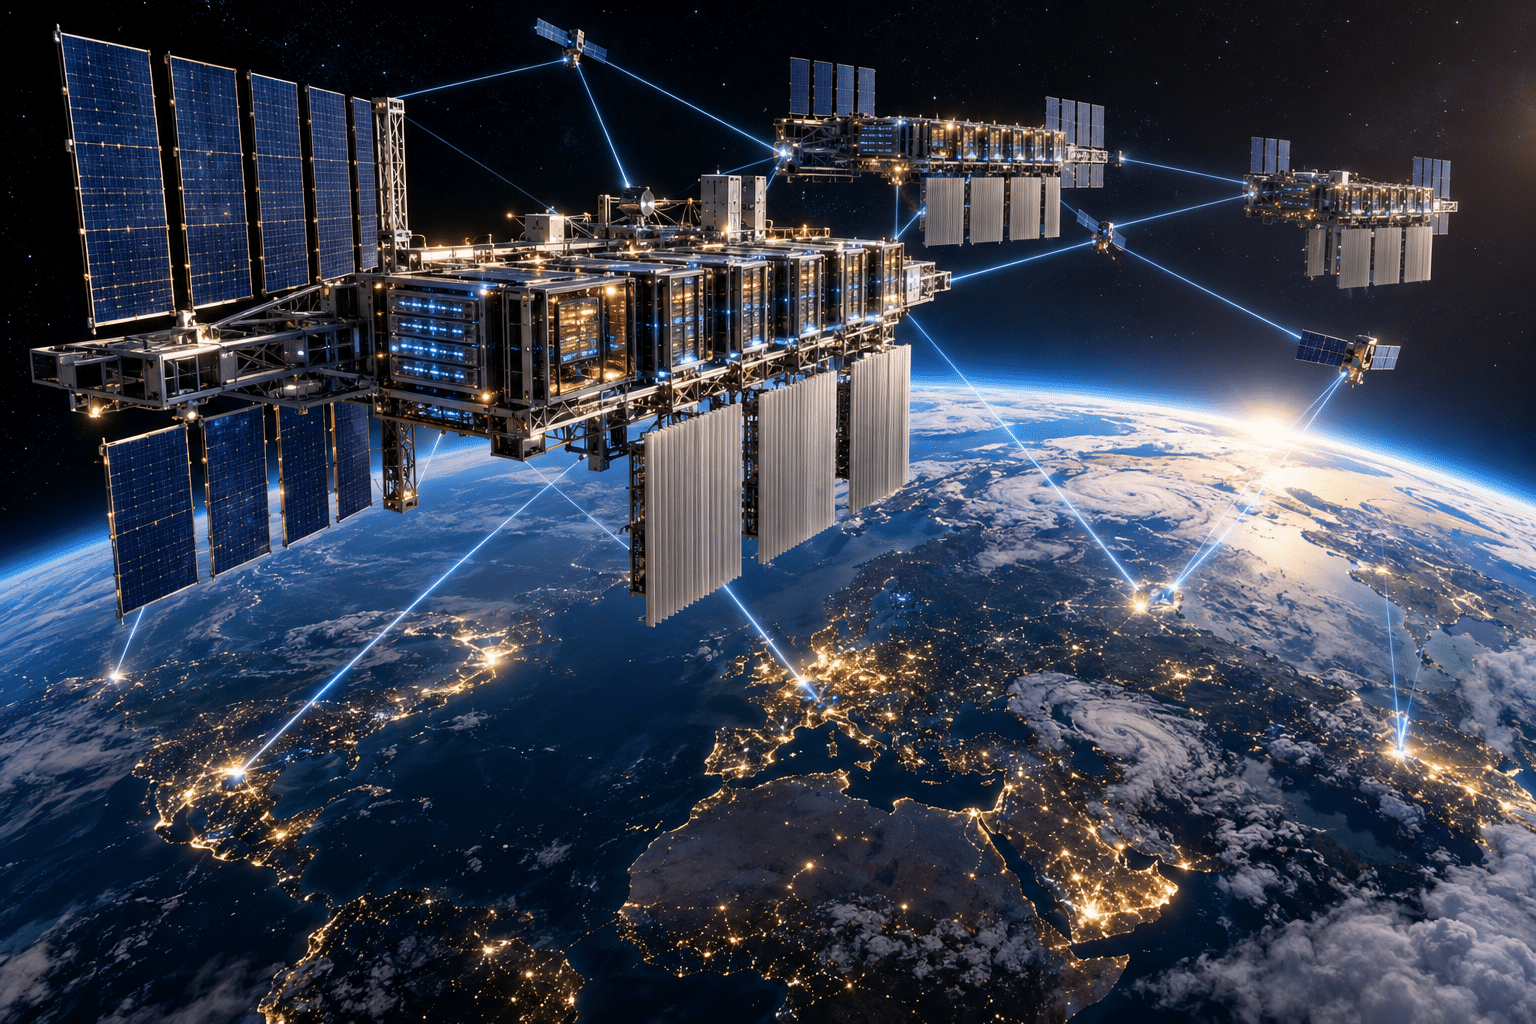
The race to build data centres in space is moving from science fiction towards an engineering experiment, driven by the enormous computing power needed to train and run artificial intelligence (AI) models.
The basic idea is straightforward: put computing hardware on satellites or large orbital platforms, connect them through high-speed communications networks and use the vacuum of space as an environment for cooling and solar energy as the power source.
Companies developing the concept argue that space could eventually offer advantages that are difficult to replicate on Earth, where data centres consume huge amounts of electricity and water and require increasingly large amounts of land and grid capacity.
Solar panels can generate electricity continuously for much of an orbital mission, while radiators can release waste heat directly into space, potentially reducing the need for the water-intensive cooling systems used by many terrestrial data centres.
The biggest obstacle, however, is getting the hardware into orbit and keeping it there.
Rocket launches remain expensive, although costs have fallen dramatically, while computing equipment must withstand radiation, extreme temperature changes and the physical stresses of launch, potentially requiring specialised hardware that is more expensive and less powerful than its Earth-based equivalent.
There is also the problem of maintenance. A failed server in a conventional data centre can be replaced within hours, whereas repairing or upgrading equipment hundreds of kilometres above Earth is considerably harder.
Moving data between space and Earth presents another challenge, particularly for AI applications that require enormous volumes of information to be transferred rapidly.
For those reasons, space-based computing is unlikely to replace conventional data centres soon, but that does not mean the concept will fail.
The most plausible early applications are specialised workloads, such as processing satellite imagery in orbit before transmitting results to Earth, rather than running massive consumer AI platforms entirely from space.
If launch costs continue falling and radiation-resistant chips, autonomous maintenance and optical communications improve, orbital data centres could eventually become economically viable for selected workloads.
The question is therefore less whether data centres can operate in space, and more whether the savings in energy, cooling and land can eventually outweigh the extraordinary cost and complexity of putting computing infrastructure into orbit.
There’s no doubt that artificial intelligence (AI) is changing the way people find information online.
Instead of visiting a news website, reading an article and seeing its advertising, a user can increasingly ask an AI search engine or assistant a question and receive an answer that is built from information published by websites.
That creates a problem for publishers: their journalism, reviews, research and other content may help an AI product answer a user’s question, but the user may never visit the publisher’s website.
Cloudflare has now proposed a way to put a price on that use.
It is called “Pay Per Use”, and unlike a traditional licensing agreement, it is designed to let AI companies pay publishers when their content is actually used rather than simply when it is crawled.
What is Pay Per Use?
The easiest way to understand Pay Per Use is to think of it as a meter for AI use of online content.
An AI company says what kind of use it is willing to pay for and how much it will pay.
For example, an AI search company could say: “We will pay when we use an article from a participating publisher as a source for an answer.”
A shopping AI company could instead say: “We will pay when information from a participating product review helps us make a recommendation.”
The publisher then decides whether to accept that offer.
If it does, the AI company can access the publisher’s content and, when that content is subsequently used in the way covered by the programme, the AI company reports the use to Cloudflare.
Cloudflare then handles the billing and pays the publisher.
Cloudflare says publishers can see their reported uses and earnings through its dashboard.
Why does Cloudflare want to pay for use rather than crawling?
This is one of the most important parts of the idea.
AI systems can crawl enormous amounts of information without necessarily using most of it.
An AI search engine might download 1,000 articles while looking for information to answer questions, but ultimately use only 10 of them.
Under a system that charges for every crawl, the AI company would pay for all 1,000 requests.
Cloudflare argues that this is not necessarily the right way to measure value.
Pay Per Use instead attempts to charge for what happens after the crawl.
The AI company may access an article without paying simply because it is researching or indexing the page, but payment can be triggered later if the content is actually used in the defined way.
That is the major difference between Cloudflare’s earlier Pay Per Crawl system and Pay Per Use.
Pay Per Crawl charges for access to content, while Pay Per Use is designed to charge when that content creates value inside an AI product.
What does this mean for publishers?
For publishers, the attraction is relatively straightforward.
Today, a publisher essentially has several choices when dealing with AI crawlers.
It can allow them to access its content, block them, or negotiate an individual licensing agreement with an AI company.
The problem with individual licensing is scale.
A major newspaper might be able to negotiate a deal with a major AI company, but a small specialist publisher is unlikely to have the time or bargaining power to negotiate separate agreements with every AI service.
Cloudflare is trying to create a common system in which the publisher does not have to build a separate technical or payment relationship with every AI company.
A publisher would see an offer in its Cloudflare dashboard, decide whether to accept it and then monitor how much its content is being used.
The publisher can also stop participating if the arrangement no longer makes sense.
Cloudflare says publishers will eventually be able to have more control over pricing, including potentially charging different amounts for different types of use.
That could become important because not every piece of content has the same commercial value.
What does it mean for AI companies?
The system is also designed to solve a problem for AI companies.
An AI company that wants to use information from thousands or millions of websites would rather not negotiate a separate commercial and technical agreement with every publisher.
Under Cloudflare’s model, the AI company integrates with Cloudflare once and can potentially connect with publishers that have opted into its programme.
The AI company defines what counts as a paid use and sets the price.
It then reports each use through an API.
Cloudflare handles the rest of the payment process.
For an AI company, that creates a potentially simpler way to obtain access to valuable material that might otherwise be blocked or placed behind a paywall.
What does this mean for ordinary Internet users?
Most users will not interact directly with Pay Per Use.
You are unlikely to see a separate payment screen every time an AI assistant uses information from a newspaper article.
Instead, the financial relationship is primarily between the AI company and the publisher.
The potential benefit for users is indirect.
If publishers can earn money when their journalism is used by AI systems, they may have a stronger financial incentive to continue producing the reporting, reviews, research and specialist information that AI systems depend on.
At the same time, AI companies could gain access to more high-quality and frequently updated information.
The cost of that access could ultimately become part of the economics of an AI product, although Cloudflare’s announcement does not establish that consumers will pay a specific additional fee.
The biggest question: can AI companies be trusted to report every use?
This is one of the most important technical questions surrounding the system.
Cloudflare’s model depends heavily on the AI company reporting when it uses content.
The buyer reports information such as when the use happened, the URL involved and an event ID.
Cloudflare says its system checks that a reported use relates to a publisher that has enrolled in the relevant programme.
But the underlying usage report is still supplied by the buyer.
That means the success of Pay Per Use will depend partly on whether AI companies reliably and completely report the uses covered by their agreements.
Cloudflare is therefore not simply building a payment system.
It is also trying to build a system for measuring and recording how AI systems use online content.
That record could ultimately be almost as important to publishers as the money itself.
What stage is Pay Per Use at now?
This is not yet a fully mature, open marketplace for every publisher and every AI company.
Cloudflare says Pay Per Use entered beta on 30 September 2026.
During the beta, Cloudflare is working directly with participating AI companies and publishers to test whether both sides want to continue using the system.
That means several important questions are still being tested.
What comes next?
Cloudflare’s longer-term ambition is to allow new AI buyers to join the system without having to create a completely new technical and payment arrangement with every publisher.
The company also wants publishers to have more control over their offers, including the ability to accept or reject offers, potentially negotiate prices and price different types of use differently.
Cloudflare is also working on giving publishers more information about how their content was used.
That could eventually include the keywords that led to a citation, the topic of the user’s request or the AI product in which the content was used, while avoiding the exchange of personal information.
In other words, the next stage is not simply making payments work.
Will Pay Per Use solve the copyright problem?
Probably not by itself.
This distinction is important.
Pay Per Use is primarily an economic and technical system, not a new copyright law.
If an AI company pays a publisher for using an article in an AI-generated answer, that can create a commercial arrangement between the two parties.
It does not automatically settle every question about whether the underlying copying, crawling, storage, training or generation was legally permitted.
For example, AI training raises different copyright questions from using an article as a cited source in an answer.
Cloudflare’s own system recognises this distinction by allowing programme terms to specify what an AI company may do with content, including restrictions relating to training.
The bigger idea
Cloudflare’s proposal is ultimately an attempt to change the economics of the Internet.
Pay Per Use is Cloudflare’s attempt to create a new link in that chain:
content → AI use → measurable value → payment to the publisher.
Whether that becomes a major new business model for the internet is still an open question.
For now, it is a beta experiment.
But if Cloudflare can persuade enough AI companies to pay, enough publishers to participate and both sides to trust the usage data, Pay Per Use could provide something the web currently lacks: a standardised way for online content to earn money even when the person consuming it never visits the website that produced it.